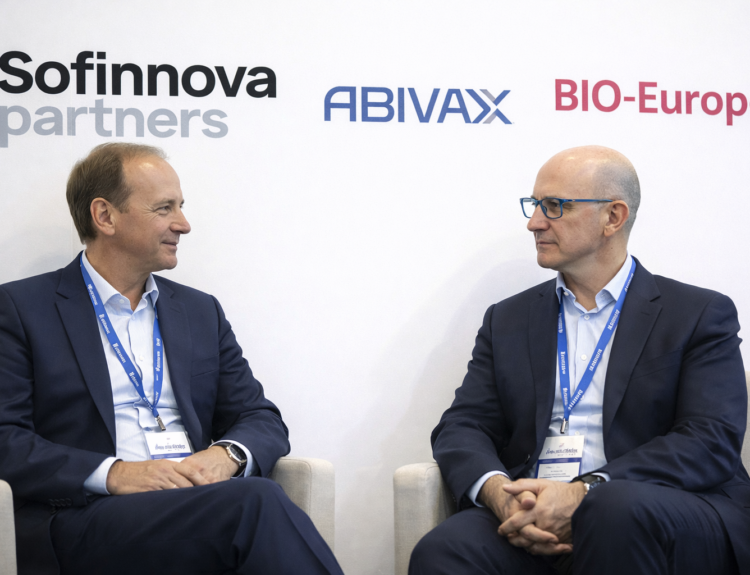


At BIO-Europe Spring 2026, the panel “Is AI at the Helm of Biopharma Business Development” Strategies? convened against a specific inflection point: generative AI has moved from isolated pilots to enterprise-wide deployment across BD functions at major pharma companies — yet the vendor landscape remains fragmented, organizational adoption is uneven, and the boundary between machine-executable tasks and human judgment remains poorly defined in most organizations. Moderator Jacqueline Poot, President of Strategic Consulting & Analytics at IDEA Pharma, led a panel comprising Carlos De Sousa, CEO at Biotech Advisor and former CEO of Ultimo Vex (successfully acquired); Luciano Lucas, Senior Director at Danaher Corporation; Dmitrii Radkevich, Head of Product at OPTIC; and Martin Svorc, Director of Neurology & Immunology and Fertility Business Development at Merck KGaA. Together, the four panelists mapped a BD function in structural transition — one where the core constraint is no longer data access, but rather organizational readiness to deploy AI at the right moments in the workflow.
The BD Workflow as a Spectrum: Data Tasks vs. Judgment Tasks
The discussion opened with a structural diagnosis that reframes how organizations should think about AI deployment: not as a monolithic capability, but as a tool whose value is asymmetric across the BD value chain. The OPTIC representative introduced a conceptual axis — data tasks at one end, judgment tasks at the other — that proved foundational to every subsequent use case discussed. Data tasks, defined as activities involving retrieval, aggregation, cross-referencing, and synthesis of structured or semi-structured information, are where current AI systems deliver near-immediate ROI. Judgment tasks — asset prioritization, partner selection, deal structuring, strategic positioning — remain domains where AI functions as a high-quality starting point rather than a decision engine.
The practical implications of this spectrum are consequential. BD teams at large pharma organizations have historically allocated an estimated 80% of their working time to manual data gathering — pulling records from databases such as Citeline or GlobalData, cross-referencing pipeline assets, reviewing company websites, and synthesizing press releases and quarterly reports — leaving only 20% of available bandwidth for strategic analysis. AI-enabled workflows invert that ratio, rebalancing toward the judgment-intensive work that drives deal quality. The Danaher representative corroborated this rebalancing from an operational standpoint: where a full due diligence previously required assembling a team of approximately ten subject matter experts before an investment decision could advance, AI-enabled first-pass analysis now allows two or three people to conduct an initial screening report and progress substantially before triggering a full technical evaluation team.
The Merck KGaA representative added granular context to the workflow map, identifying the BD value chain as comprising four discrete stages — search and evaluation, due diligence, contracting, and alliance management — each of which has been stress-tested for AI applicability over the past two years. Competitive landscaping, which previously required manual queries across multiple legacy databases known to have incomplete coverage and outdated asset information, can now be assembled in hours using generative AI, with human review focused on verification and strategic interpretation rather than data assembly. This is not a marginal efficiency gain: the reduction in time-to-landscape directly accelerates the triage decision that determines which assets receive deeper evaluation resources.
One documented failure case illustrates the current ceiling for AI-driven search. In a structured five-vendor evaluation for an asset search and evaluation use case, the Merck KGaA team found that the breadth of coverage achievable through AI-agentic tools did not yet match the comprehensiveness of established legacy databases — a gap the team explicitly attributed to the current state of foundational model capability and vendor data integration, not to the AI paradigm itself. The use case was shelved pending re-evaluation in six to twelve months, a timeline calibrated to the pace of foundational model updates, which the Merck KGaA representative characterized as occurring on roughly a semi-annual cycle.
Deployment Architecture and Case Studies Across Organization Types
Within this environment of structured experimentation, two distinct deployment architectures emerged from the panel — one suited to large, multi-company organizations with complex data governance requirements, and one applicable to small biotech teams operating under resource constraints where time compression and cost reduction are the primary value drivers.
At Merck KGaA, the adoption model is built around a voluntary innovation cohort of ten individuals drawn from across BD roles, tasked with generating and piloting new use cases before any tool or workflow reaches the broader team. The explicit expectation is that most pilots will fail — and that this failure rate is a feature, not a defect, of responsible AI adoption at this stage of the technology’s maturity. Only use cases that survive this internal filtration process are advanced to the full BD team, typically championed by the individual who validated them. This champion-driven rollout model creates organic buy-in: colleagues who observe a peer saving substantial time on a specific task become self-motivated adopters rather than reluctant compliance cases. Training operates on two parallel tracks — a baseline layer covering everyday AI functionality such as email summarization and document drafting, and a tool-specific layer delivered either by vendors or internal resources, calibrated to the particular workflow being deployed.
The alliance management application at Merck KGaA represents one of the more architecturally specific implementations discussed. Alliance managers working on existing deals routinely produce contract amendments, side letters, and related legal instruments that require drafting precision but do not carry the complexity of originating licensing agreements. A generative AI system trained on the company’s own contract templates and historical examples now handles the initial drafting of these instruments, with legal review concentrated at the final sign-off stage rather than distributed across the full drafting cycle. The structural effect is a reallocation of legal resources from low-complexity drafting to high-value review — preserving legal judgment where it matters while removing it from the bottleneck of routine document production.

The OPTIC representative offered a case study that illustrates how organic AI transformation can be triggered through a single, well-scoped implementation. A biopharma investment firm attempted a broad, top-down AI transformation initiative and failed to achieve adoption. After reorienting to a focused deployment — generating five automated mini-due-diligence reports daily, delivered each morning to a BD professional ahead of company meetings, covering pipeline status, clinical data, and a pre-populated list of targeted questions — that individual became an internal advocate who drove AI adoption across the organization from the bottom up. The lesson is structural: forced enterprise transformation generates resistance, while demonstrated personal productivity gains generate pull.
At Danaher, the critical enabling factor was not the AI tool itself but the resolution of data governance barriers between the corporation’s multiple operating companies. An early enterprise AI deployment that allowed users to query internal data produced limited value because legal constraints on cross-company data sharing effectively siloed each user within the narrow scope of their own email archive. As those legal frameworks were progressively addressed, the same underlying tool became capable of cross-referencing due diligence data rooms, historical meeting notes, and enterprise documents spanning multiple years and business units — a capability the Danaher representative characterized as a qualitative shift in analytical power, not merely an incremental improvement. The implication for any multi-entity organization is that AI tool selection is downstream of data architecture: without AI-ready, legally accessible enterprise data, even well-designed tools produce constrained outputs.
For small biotech teams — operating without dedicated BD infrastructure, legal resources, or the budget to run multi-vendor pilot programs — the value proposition of AI compresses around three specific pain points: competitive intelligence gathering, IP analysis, and regulatory document preparation. The Investigator’s Brochure, a document of substantial length and complexity that aggregates preclinical and clinical data to inform trial site personnel, was cited as a concrete example of AI-assisted preparation that reduces both the time burden and the cost of production for lean teams. The former biotech CEO on the panel noted that IP diligence, which typically requires specialist legal input that is both expensive and slow, represents another high-leverage application for AI-assisted first-pass analysis — with the caveat that the output requires expert verification before any deal-critical decision is made.
Hallucination Risk, Source Traceability, and the Responsible AI Architecture
The most architecturally specific segment of the discussion addressed how AI platforms should be structured to make their outputs usable in high-stakes BD contexts — where errors introduced into a competitive landscape or due diligence report can propagate into deal terms, governance presentations, or investment decisions.
The core technical problem is that large language models are optimized to generate responses rather than to acknowledge ignorance. When forced to answer a question beyond their knowledge boundary, they produce plausible-sounding fabrications with no internal signal distinguishing them from verified facts — a property that makes unvalidated AI output categorically unsuitable for BD governance submissions. The OPTIC representative described the platform’s architectural response to this problem: the AI agent is designed to expose every reasoning step, every source citation, and every specific data point or quote used to reach a conclusion, enabling the human reviewer to audit the chain of inference rather than simply accepting the output. Additionally, the system is trained to return a null or low-confidence response — explicitly flagging insufficient data or low-quality sourcing, including categorical rejection of unverified reference sources such as Wikipedia — rather than generating a confident but unsupported answer. This architecture functionally converts the AI agent from a black-box output generator into a transparent analytical assistant whose work product can be checked at the level of individual claims.
The Danaher representative framed the same risk at a higher level of abstraction: AI systems do not generate new knowledge — they recombine existing knowledge. In domains where the underlying data is sparse, outdated, or structurally biased toward positive results (as is the case with most published clinical data), the model’s output will reflect those gaps without necessarily signaling them. This is not a solvable software problem; it is an epistemological constraint that requires human domain expertise to identify and compensate for. The practical implication is that AI augments expert judgment — it does not substitute for it.
The OPTIC representative also surfaced a specific capability that illustrates AI’s analytical leverage in data-dense domains: the ability to answer questions that were structurally difficult to formulate before AI-enabled natural language querying. An example given — identifying all drugs that demonstrated clinical efficacy in a particular indication space but were discontinued for safety reasons, cross-referenced against off-label use patterns in the same indication — represents a query that would previously have required weeks of manual database work and likely produced incomplete results. That same query now resolves in hours, with source traceability, enabling BD teams to identify repositioning opportunities or competitive safety signals that legacy database interfaces were structurally incapable of surfacing.
Market Structure, Organizational Readiness, and the Forward Trajectory
Looking ahead, the panel converged on a view that the current vendor landscape — characterized by abundant funding, proliferating point solutions, and limited differentiation between genuine capability and well-funded marketing — will consolidate into a tiered market structure over the next one to three years. The Merck KGaA representative, having run a structured five-vendor evaluation for a single use case, anticipated a segmentation into specialized verticals: dedicated legal AI tools, due diligence platforms, competitive intelligence engines, and foundational models providing broad base-layer service to customers who cannot or will not pay for vertical specialization. The winner-selection process will be driven by proven enterprise deployments — the accumulation of validated use cases in production environments — rather than by demonstration performance.
A pointed observation from the small biotech perspective reframed the competitive stakes of AI adoption: companies that fail to develop AI-native BD capabilities will be at a structural disadvantage not just in speed, but in the quality and coverage of their strategic analysis — and those disadvantages will compound as AI-enabled competitors move faster through the search-evaluate-diligence cycle. Boards and investors are already beginning to expect AI deployment, often with inflated assumptions about capability, which creates a secondary organizational challenge: educating governance stakeholders — VCs, board members, executive committees — about the genuine capabilities and limitations of current tools to prevent expectation mismatches that generate credibility erosion when pilots underperform.
The Danaher representative distilled the organizational prerequisites for AI transformation into three vectors: data readiness (breaking down data silos and making enterprise information AI-accessible); culture (developing internal champions who demonstrate value organically rather than imposing top-down mandates); and epistemic humility (building organizations that understand AI systems cannot generate knowledge that does not yet exist, and that calibrate their use cases accordingly). Of these, the data readiness vector is the most frequently underestimated — not because it is technically complex, but because it requires sustained legal and governance work that is unglamorous and often deprioritized relative to tool procurement.
One forward-looking provocation from the panel deserves particular attention: as AI tools gain access to comprehensive clinical trial databases, efficacy endpoints, and safety records, they become capable of generating objective comparative assessments of a biotech’s asset positioning versus its competitive field — on primary endpoints, secondary endpoints, and endpoint scaling — faster than any human analyst and without the confirmation bias that characterizes internally produced clinical summaries. The scenario in which an AI system returns a frank assessment to a board or investor group that an asset’s data profile does not support the projected commercial trajectory is no longer hypothetical; it is a near-term operational reality for any organization that deploys these tools at scale. How governance structures respond to AI-generated critical assessments of their own portfolios will define whether the technology is used as a genuine decision-support system or merely as a productivity tool that reinforces existing strategic commitments.

Moe Alsumidaie is Chief Editor of The Clinical Trial Vanguard. Moe holds decades of experience in the clinical trials industry. Moe also serves as Head of Research at CliniBiz and Chief Data Scientist at Annex Clinical Corporation.